Data Engineer resume example
By Bhagirath Sheela, founder of JobCatch ·
Data engineers are hired to make data reliable and fast to use. A good resume names the pipelines you built, the volumes and freshness they achieved, the tools in the modern data stack, and what broke less after you arrived.
What recruiters look for
- Pipelines and volumes: rows or terabytes a day, latency, freshness
- SQL, Python and Spark, plus an orchestrator such as Airflow
- Warehouses and lakes: Snowflake, BigQuery, Redshift, Delta Lake
- Data quality, cost control and reliability
Section order
With experience
- Summary
- Skills
- Experience
- Projects
- Education
- Certifications
As a fresher
- Summary
- Education
- Skills
- Projects
- Internships
- Certifications
Summary examples
Fresher
Data engineer with a B.Tech in computer science and an internship building Airflow pipelines into Snowflake. Strong SQL and Python; certified in Google Cloud data engineering basics.
Experienced
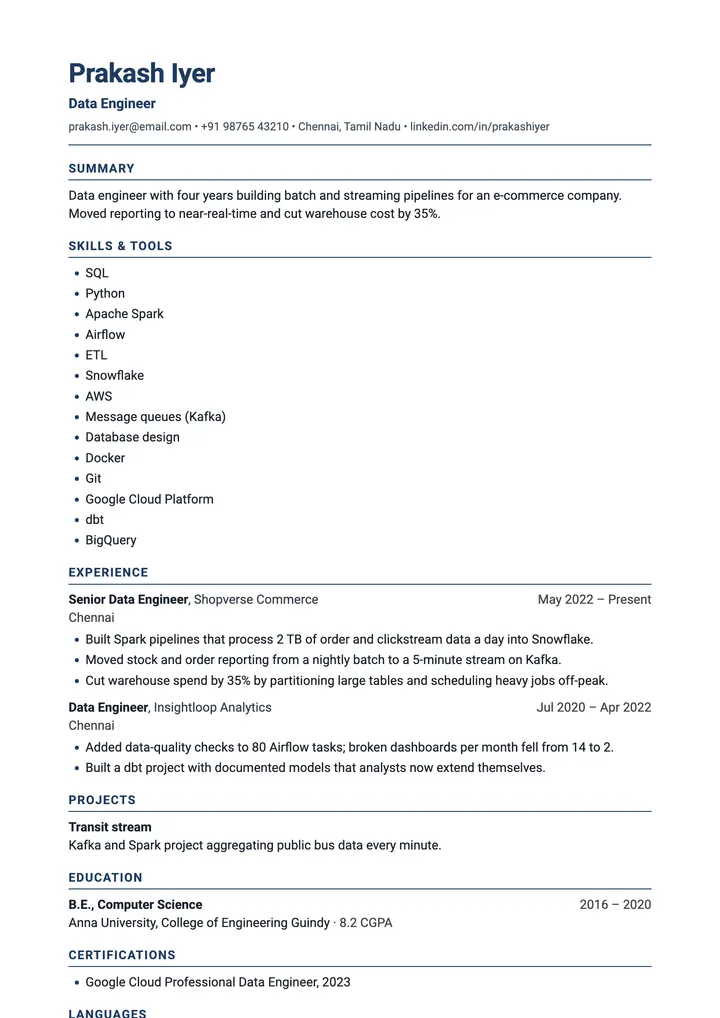
Data engineer with four years building batch and streaming pipelines for an e-commerce company. Moved reporting to near-real-time and cut warehouse cost by 35%.
Skills, spelled the way postings spell them
An applicant tracking system matches the words in the job posting, and it does not reliably treat two spellings as one skill. The left column is the form most postings use; the right, other spellings people type. Use the posting's own spelling for each application, and list only what you can discuss in an interview.
| Skill | Also written as |
|---|---|
| SQL | Structured Query Language |
| Python | Python 3 |
| Apache Spark | Spark, PySpark |
| Airflow | Apache Airflow |
| ETL | Data pipelines, ELT |
| Snowflake | — |
| AWS | Amazon Web Services |
| Message queues (Kafka) | Kafka, Apache Kafka |
| Database design | Schema design, Data modelling, Data modeling |
| Docker | Containerisation, Containerization |
| Git | Version control, GitHub, Bitbucket |
| Google Cloud Platform | GCP, Google Cloud |
Also worth listing if you have them: dbt, BigQuery.
Bullet examples
Each bullet says what you did and what changed because of it. Change the numbers to your own; a recruiter will ask about every one.
- Built Spark pipelines that process 2 TB of order and clickstream data a day into Snowflake.
- Moved stock and order reporting from a nightly batch to a 5-minute stream on Kafka.
- Cut warehouse spend by 35% by partitioning large tables and scheduling heavy jobs off-peak.
- Added data-quality checks to 80 Airflow tasks; broken dashboards per month fell from 14 to 2.
- Built a dbt project with documented models that analysts now extend themselves.
For freshers: projects and internships
- Internship: built Airflow pipelines that load ad-spend data from three APIs into Snowflake daily.
- Built a streaming project with Kafka and Spark that aggregates public transit data every minute.
- Designed a star schema for a college library's borrowing data and wrote the SQL reports on it.
Mistakes to avoid
- No volumes. "Built ETL pipelines" could be a spreadsheet; "2 TB a day" could not.
- Leaving out reliability and cost. Data engineers are judged on what breaks and what it costs.
- A tool list with no architecture. Say how the pieces fit: source, transport, storage, transformation.
What an ATS reads from this sample
An applicant tracking system turns the PDF into plain text before anyone reads it. This is that text for the sample above, extracted by the same code as "What the ATS reads" in the app. Everything is in reading order, under the right heading, with the name and email intact — which is what a single-column template is for.
Prakash Iyer

Data Engineer

[email protected] • +91 98765 43210 • Chennai, Tamil Nadu • linkedin.com/in/prakashiyer

Summary

Data engineer with four years building batch and streaming pipelines for an e-commerce company. Moved reporting to near-real-time and cut warehouse cost by 35%.

Skills & Tools

SQL

Python

Apache Spark

Airflow

ETL

Snowflake

AWS

Message queues (Kafka)

Database design

Docker

Git

Google Cloud Platform

dbt

BigQuery

Experience

Senior Data Engineer, Shopverse Commerce
May 2022 – Present

Chennai

Built Spark pipelines that process 2 TB of order and clickstream data a day into Snowflake.

Moved stock and order reporting from a nightly batch to a 5-minute stream on Kafka.

Cut warehouse spend by 35% by partitioning large tables and scheduling heavy jobs off-peak.

Data Engineer, Insightloop Analytics
Jul 2020 – Apr 2022

Chennai

Added data-quality checks to 80 Airflow tasks; broken dashboards per month fell from 14 to 2.

Built a dbt project with documented models that analysts now extend themselves.

Projects

Transit stream

Kafka and Spark project aggregating public bus data every minute.

Education

B.E., Computer Science
2016 – 2020

Anna University, College of Engineering Guindy · 8.2 CGPA

Certifications

Google Cloud Professional Data Engineer, 2023

Languages

English · Hindi
Interview questions to prepare
The app's interview prep for this sample and a plain Data Engineer posting. It works from the resume and the posting only, and tells you how to prepare, never what to say.
Questions every interview has
- Tell me about yourself. Two minutes: what you do now (Senior Data Engineer at Shopverse Commerce), one result you are proud of, and why this role is next.
- Why do you want this job? Read their website and one recent piece of news before the call. Name something specific.
- Why are you leaving your current job? Say what you are moving towards. Do not criticise your employer.
- What is your notice period, and what salary are you expecting? Decide your number before the interview, so you are not deciding it on the call.
About the skills the job asks for
- Tell me about a time you used Python. Pick one real example: what the problem was, what you did, and what changed.
- Tell me about a time you used SQL. Pick one real example: what the problem was, what you did, and what changed.
- Tell me about a time you used ETL. Pick one real example: what the problem was, what you did, and what changed.
- Tell me about a time you used Apache Spark. Pick one real example: what the problem was, what you did, and what changed.
- Tell me about a time you used Airflow. Pick one real example: what the problem was, what you did, and what changed.
- Tell me about a time you used Snowflake. Pick one real example: what the problem was, what you did, and what changed.
About what the resume claims
- You wrote: "Built Spark pipelines that process 2 TB of order and clickstream data a day into Snowflake." Expect three follow-ups: how exactly, what was your own part, and how you know it worked.
- You wrote: "Moved stock and order reporting from a nightly batch to a 5-minute stream on Kafka." Expect three follow-ups: how exactly, what was your own part, and how you know it worked.
- You wrote: "Cut warehouse spend by 35% by partitioning large tables and scheduling heavy jobs off-peak." Expect three follow-ups: how exactly, what was your own part, and how you know it worked.
Questions to ask them
- What would a good first three months in this role look like?
- Who would I work with most closely?
- What are the next steps, and when should I expect to hear back?
Templates that suit this role
All of these are single-column and read cleanly by an applicant tracking system. Classic is free, with no watermark.
Questions
What is the difference between a data engineer and a data analyst resume?
An analyst's bullets end in business decisions; a data engineer's end in pipelines that are faster, cheaper or more reliable. Both need strong SQL.
Is Spark required for data engineering jobs?
It appears in most postings for experienced data engineers in India. Freshers can start with SQL, Python and an orchestrator, but learning Spark (or PySpark) widens the field a lot.
Next: the Data Engineer cover letter the app drafts from this resume, and how to show SQL, Python, Apache Spark on a resume.
More data & ai resume examples: Data Analyst · Business Analyst · Data Scientist · Machine Learning Engineer · AI Engineer · Power BI Developer · SQL Developer